1–3 seconds · 60 original frames
Original referenceLanczosRealESRNetReal-ESRGAN faces OFFRealBasicVSR faces OFF
EXPERIMENT 002 · 320 × 180 → 720p
A home-video restoration test. Keep familiar faces, expressions, and movement faithful to the footage.
THE FINDINGS SO FAR
The goal is faithful home video. Aunt Jane should still look like Aunt Jane. A useful result preserves faces, expressions, and movement; extra apparent sharpness is useful only when it supports that goal.
What we tried: an 8.37-second, 1920 × 1080 home-video clip was reduced to 320 × 180, then enlarged to 1280 × 720 using Lanczos, RealESRNet, Real-ESRGAN and RealBasicVSR. All start from the same lossless small master. Face enhancement, face replacement, extra sharpening, and frame interpolation are off in this main comparison. Real-ESRGAN and RealBasicVSR still use learned generative priors without a face enhancer. All generated videos are silent, and the camera source is preserved.
How to read the page: the main comparison shows the 320 × 180 input beside the selected upscale, so you can judge what processing adds or changes. The original remains available as a reference for checking whether those changes are faithful.
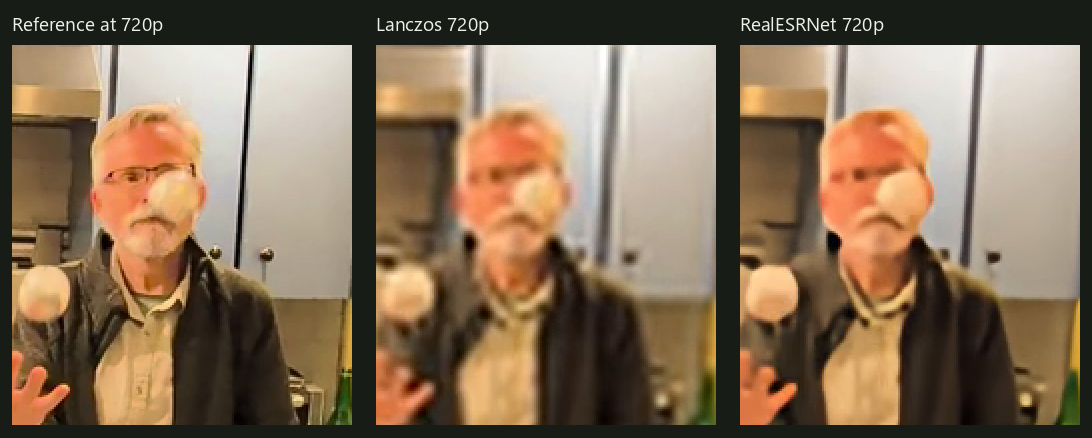
What the comparison shows: Lanczos gives a soft enlargement. RealESRNet smooths and strengthens outlines, but the inspected face crop still lacks the reference’s fine facial and glasses detail. We have a working neural upscale, with facial fidelity still to be judged across the clip. A clean synthetic downscale is an easier task than many noisy, compressed old recordings.
Interesting local detail: on this Windows desktop, Lanczos took 1.63 seconds on the CPU. RealESRNet took 47.33 seconds for processing and encoding on the RX 6700 XT, plus 0.81 seconds to load the model. All 251 frames were retained. These are individual runs on this clip; they do not predict Mac performance. Run record ↗
Fidelity and motion: RealESRNet has the highest measured PSNR and SSIM of the four methods against the matched original, including the fixed face region. RealBasicVSR uses information across frames, but a fidelity improvement is not established here. The scores measure similarity on one clean synthetic test, not facial identity or archive-wide quality. Inspect the measurements and five-column motion loops ↓
A working temporal-model experiment: after a two-second trial, RealBasicVSR processed the full clip as one bidirectional sequence. Its older framework needed a small PyTorch adapter; a source-integrity check and CPU/GPU numerical spot check are recorded, with the limits of that validation. Keep the result experimental and inspect faces through motion. Full run record ↗ · Adapter validation ↗
The model shortlist needed updating. SeedVR2, FlashVSR/FlashVSR+ and DOVE are newer video-oriented diffusion candidates. They have not been run here. SeedVR2’s maintained ComfyUI route documents ROCm and Apple Silicon support, making it the most plausible next local smoke test; compatibility and fidelity on this 6700 XT remain unmeasured. Current sources and practical limits ↓
A separate generative stress test: Real-ESRGAN + GFPGAN at 720p ↗ allows generated facial detail, with face reconstruction on. It is a creative derivative for inspecting deviation; it has not been accepted as a faithful restoration.
FOR MAC USERS
There are free, open-source ways to do this locally on Apple Silicon. Start with a short sample, retain the original, keep its aspect ratio, and compare faces in motion before choosing a method. Software support below is documented; we have not run these Mac versions.
| Route | How to use it | What is documented |
|---|---|---|
| FFmpeg + Lanczos ↗The conservative starting point | Install FFmpeg with Homebrew and resize a copy. It interpolates existing pixels without a learned face-restoration model. | Homebrew provides Apple Silicon packages. This is the same conventional resize method used in our test. |
| REAL Video Enhancer ↗A video-oriented graphical interface | Use the free GitHub MacOS_arm64 release. Choose a model intended for live-action footage, disable interpolation, and check a short output first. | The project lists macOS 15+ ARM support and publishes a Mac ARM build. Its output depends on the selected model; it is not an exact reproduction of our RealESRNet run. |
| ComfyUI locally ↗For testing the same model | Load RealESRNet_x4plus and use an image-upscale workflow without a face enhancer. Use a video/frame-batch workflow for the full sequence, then encode with FFmpeg. | Comfy Desktop lists M1 or newer and macOS 13+. PyTorch’s current MPS requirements also apply; Apple currently lists macOS 14+ for its stable setup. |
With Homebrew installed, run brew install ffmpeg. Download the silent lossless small master, open Terminal in that folder, and run:
ffmpeg -n -i "downscaled-320x180-lossless.mkv" -vf "scale=1280:720:flags=lanczos,setsar=1" -an -c:v libx264 -preset medium -crf 16 -pix_fmt yuv420p -color_primaries bt709 -color_trc bt709 -colorspace bt709 -movflags +faststart "lanczos-720p.mp4"This command matches our 16:9 SDR test. For 4:3 home video, keep a 4:3 picture, such as 960 × 720, or add side bars inside a 1280 × 720 frame. HDR footage needs a consistent colour-conversion plan before comparison.
To try the same neural model, install ComfyUI locally, put RealESRNet_x4plus.pth in its models/upscale_models folder, and test a few frames with Load Image → Load Upscale Model → Upscale Image (using Model) → Save Image. Apple GPU acceleration uses Metal/MPS. For a full video, add a video or frame-batch workflow and preserve the source frame order and rate when encoding. Our current Windows/ROCm script is not a ready-made Mac runner.
Upscayl is another free Mac option for images; video requires a frame-extraction and reassembly workflow. For M1 through M5, check the current app, macOS, and memory requirements for the particular machine. Start with FFmpeg’s baseline; use the same face-fidelity checks for any neural model. Mac sources checked 17 October 2026; no Mac speed or quality claim is based on local testing.
Loading comparison…
Space: play / pause · ← →: step framesThe same small source. All four 720p methods start from the lossless 320 × 180 SDR master. Lanczos interpolates pixels; RealESRNet and Real-ESRGAN process each frame independently. RealBasicVSR aligns and combines information across the sequence. No face enhancer, extra sharpening, or new frames were added. Face enhancement off does not guarantee honest fine detail.
Input versus output. Paired and wipe views use the downscaled input as the baseline. It is enlarged by the browser to match the output’s display size; Actual size shows its native dimensions. Select Original reference for a fidelity check, or use All six.
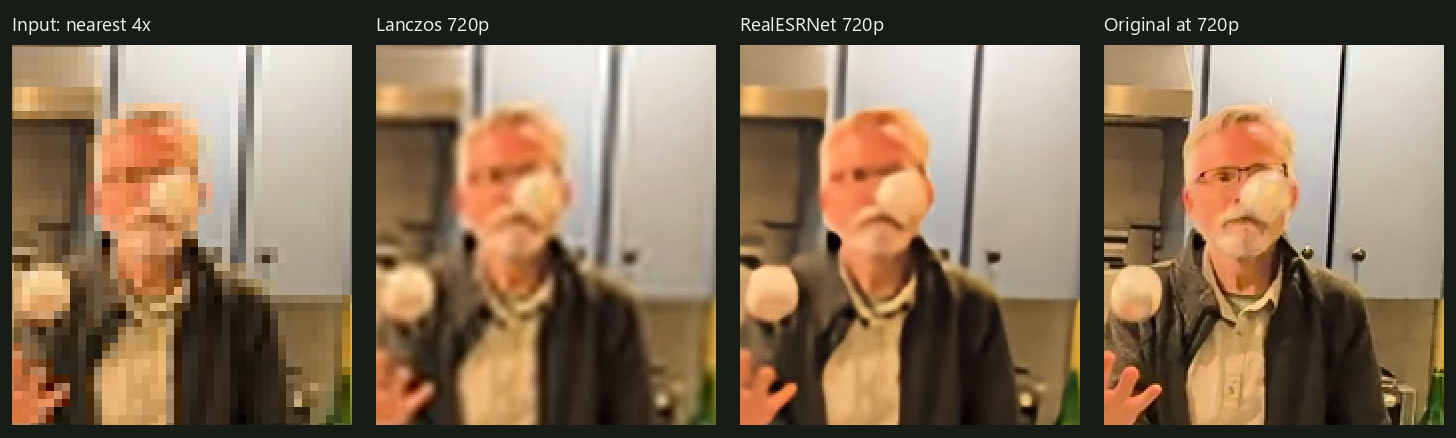
This earlier four-way spot check predates the Real-ESRGAN-only run; the motion report below includes it. The input is enlarged 4× with nearest-neighbour sampling to expose its existing pixels. Each matching 720p crop is then enlarged 2× for inspection. The original reference is resized from the full-resolution SDR copy. One frame cannot establish identity fidelity.
MEASURED SIMILARITY · HUMAN MOTION REVIEW
The downscaled input remains the main comparison baseline. For this report only, the retained original supplies a reference: the same HDR-to-SDR conversion, Lanczos resized to 1280 × 720 and stored losslessly. Every output frame is paired by index, with no frame interpolation or dropped frames.
| Method | Whole PSNR (dB) | Whole SSIM | Face-region PSNR (dB) | Face-region SSIM |
|---|---|---|---|---|
| Lanczos | 29.53 | 0.9037 | 26.39 | 0.8414 |
| RealESRNet | 31.03 | 0.9348 | 27.80 | 0.8899 |
| Real-ESRGAN · faces off | 29.58 | 0.9173 | 27.11 | 0.8722 |
| RealBasicVSR · faces off | 27.96 | 0.8823 | 27.57 | 0.8836 |
What the numbers support: RealESRNet is closest to the reference by both measures, across the whole picture and the fixed face region. RealBasicVSR combines information across frames, but has lower similarity here; this run does not establish a fidelity improvement. Sharper-looking edges alone do not establish better reconstruction.
These are decoded 8-bit YUV420 PSNR/SSIM scores, including each candidate’s H.264 CRF16 export. They do not measure identity, perceived quality or flicker. The face region is a fixed 220 × 240 window at x=620, y=180; it includes background and occluding balls and is not a tracked or biometric face measurement. One clean synthetic downscale cannot stand in for a real archive.
Download all per-frame scores, hashes and methodology ↗ · PSNR definition ↗ · SSIM definition ↗
Each strip contains five crops encoded together, including RealBasicVSR, so their frame order stays matched. Inspect glasses, mouth shape, outlines and the ball crossing the face. Choose normal or half speed. The crops use 2× nearest-neighbour enlargement; on a small screen, scroll sideways to inspect each column. These are inspection aids, not a measured temporal-stability score.
A reasonable human review records whether facial proportions, expression and frame-to-frame appearance remain acceptable. No owner acceptance or identity-fidelity score has been established. The face-reconstructed output and its numbers remain on the separate generative page.
SEPARATE EXPERIMENT · FACE RECONSTRUCTION ON
A second 720p derivative uses Real-ESRGAN plus GFPGAN’s generative facial prior. Inspect synchronized input/output playback, an optional original reference, and matched crops at three moments. This is an aggressive GAN example; it does not establish the limit of generative video restoration.
Open the separate generative stress test →A RECORD OF THE WORK
Completed steps, observations, and research are recorded separately here. New experiments will be added as further entries; earlier results remain part of the record.
Inspected the 1920 × 1080 HLG HDR camera clip: 8.37 seconds, 251 frames, 16:9. Chose 320 × 180 to retain that shape. Made a matched SDR reference, small MP4, and lossless FFV1 small master, preserving the original file.
Source, conversion recipe, and hashes ↗Set the acceptance criterion: people should remain recognisable. Removed audio tracks from the generated videos, added a silent copy of the original picture, and removed the sound control. Verified that removing audio left the encoded video data and all 251 frames unchanged.
Audio-removal verification ↗Ran the conventional baseline from the silent lossless small master. Processing and H.264 encoding took 1.63 seconds on the CPU. The output contains all 251 frames and no audio.
Silent Lanczos result ↗Passed a one-frame smoke check, then processed the full clip with RealESRNet_x4plus on the RX 6700 XT using ROCm and FP32. Processing and encoding took 47.33 seconds, plus 0.81 seconds model loading. Face enhancement, face replacement, extra sharpening, and interpolation were off. All 251 frames are present and silent.
Model hash, settings, runtime, and output checks ↗Added the selector, All four view, wipe, and shared playback and frame stepping. Verified decoding and dimensions, matched BT.709 colour signalling, and equal paused timestamps. Corrected omitted colour tags without changing decoded video samples. The 2-second face crop shows strong RealESRNet smoothing and missing fine detail. This is a limited visual observation; facial fidelity across the full clip remains to be reviewed.
Matched reference / Lanczos / RealESRNet crops ↗Checked the projects’ own documentation and release assets for FFmpeg, REAL Video Enhancer, ComfyUI, PyTorch MPS, and Upscayl. Added the Mac guide at the end of the executive summary. No Mac software has been installed or benchmarked in this experiment.
Mac guidance and primary sources ↑Made the 320 × 180 downscaled clip the fixed baseline in paired and wipe views. The selected upscale appears beside it at an equal display size. Kept the original as an optional reference and in All four, and added the input to the facial-detail comparison. The earlier three-column crop is preserved with entry 05.
Input / Lanczos / RealESRNet / original crops ↗Prepared a silent public edition with machine paths and camera location metadata excluded. Publication review identified unnecessary downloads of hidden videos. The page now loads only the input and selected comparison initially; the original reference and other upscale load when selected, or in All four. Playback uses the small input as its clock and waits for decoded frames before declaring a selection aligned.
Separated stopping playback from aligning the compared videos. Pause now waits for decoded seeks before reporting alignment, and a failed or superseded seek cannot report success. Verified that Previous moves back one displayed frame both between timestamps and on a frame timestamp; retained that behavior with regression checks.
Processed the same lossless small master with RealESRGAN_x4plus and GFPGAN v1.4 face reconstruction on the RX 6700 XT. Kept all 251 frames, stripped audio and metadata, and preserved the faithful comparison. Generated facial detail is assessed against the input and original at matched moments; successful execution is not identity acceptance.
Separate generative demo and run record ↗The first release took about 34 minutes from the first remote handoff through live checks. Late player fixes, repeated handoffs, test setup discovery and a failed review request added avoidable work. The updated procedure freezes and checks the local bundle before handoff, transfers only changed files, reuses browser fixtures, and requests review of the exact head immediately. Review and public-file verification remain part of publication. This is a procedure change; no general speedup is claimed from one release.
Ran all 251 frames through RealESRGAN_x4plus on the RX 6700 XT, FP32, without importing GFPGAN or processing faces. Kept the source and small master unchanged, retained 720p/30 fps, and verified a full decode with zero audio streams. Added the output as a selectable main comparison; the GFPGAN result stays separate.
Settings, weight hash and run evidence ↗Built a losslessly stored 720p reference directly from the camera source using the existing SDR conversion. Compared every frame with PSNR/SSIM, for the whole picture and a fixed face region. Added two 60-frame motion loops. RealESRNet has the highest similarity scores here; these measurements do not certify identity or temporal stability.
Original four-method report, including the separate generative measurement ↗Checked the official SeedVR2, FlashVSR/FlashVSR+ and DOVE projects on 17 October 2026. These are newer video diffusion routes; their published results are not local results or proof of identity preservation. SeedVR2’s ComfyUI ROCm route is the most plausible next compatibility test on this machine.
Sources and hardware constraints ↓At Adrian’s suggestion, tested RealBasicVSR (CVPR 2022). A four-frame smoke test passed, followed by a 60-frame, two-second 720p sequence in 22.99 seconds of GPU inference, plus 1.11 seconds loading, with 2.45 GiB peak tensor allocation. Face enhancement stayed off. This temporal model uses GAN training, so it can still synthesize detail. The short trial did not beat RealESRNet’s similarity scores.
Processed all 251 frames as one bidirectional sequence: 235.73 seconds inference, plus 1.09 seconds loading, with 7.96 GiB peak tensor allocation. Encoding is outside that inference timer. All frames fully decoded at 720p/30 fps with no audio; input hashes are unchanged. The adapter loads all 320 EMA state entries from the authors’ checkpoint and uses unmodified, pinned OpenMMLab network methods with a small framework shim. On a two-frame crop, CPU and ROCm FP32 outputs agreed within 0.0000042. This is a limited numerical check, not certification of the old framework or facial identity.
Full run record ↗ · Source integrity and numerical check ↗ · Same-frame short/full context comparison ↗RESEARCH UPDATE · 17 OCTOBER 2026 · NOT RUN HERE
The current GANs are useful, small baselines, but they are not a survey of today’s strongest video-restoration models. Recent video diffusion methods are worth testing for apparent detail and consistency in motion. Published benchmark improvements do not establish faithful reconstruction of a particular family member.
| Candidate | What is newer | Practical next step |
|---|---|---|
| SeedVR2 · ICLR 2026 | One-step video diffusion restoration. The authors warn of over-generated detail, heavy-degradation failures and difficult motion. | The maintained ComfyUI implementation documents ROCm, Apple Silicon/MPS, smaller models, quantization and offloading. Best next local compatibility probe: a short multi-frame 720p batch, recording exact weights/settings. No 6700 XT speed, memory-fit or identity claim yet. |
| FlashVSR · CVPR 2026 FlashVSR+ · October 2026 | Streaming one-step video diffusion; the newer Plus release provides code and weights with updated attention and post-training. | The official original relies on a specialized sparse-attention backend. Plus explicitly requires Linux/NVIDIA CUDA, despite having an SDPA attention fallback. Neither is a documented drop-in route for this Windows AMD machine. Treat author speedups as benchmark-specific, not an AMD forecast. |
| DOVE · NeurIPS 2025 | Video diffusion restoration based on CogVideoX, with released inference code and weights, including a smaller DOVE-2B option. | A worthwhile research comparison after checking dependencies and memory with a tiny run. Spatial tiling and temporal chunks are documented; AMD compatibility and performance on this system remain unverified. |
Proposed next experiment: SeedVR2 through its maintained ComfyUI implementation, isolated from this working environment. Start with a short sequence rather than one still, keep face enhancement and interpolation off, and compare against the same reference. It would belong in the separate generative area because a video diffusion model can synthesize detail without a separate face enhancer.
“Newer” and “more convincing” are not substitutes for “closer to the source.” No new model downloads, cloud uploads, paid services or changes to the shared ComfyUI installation were needed for this research update. Our Real-ESRGAN + GFPGAN example is not a ceiling on current generative restoration quality.